Measured, auditable AI
We don’t guess which AI to use. We measure.
We benchmark the field, route each job to the model that proves best, and make every answer trace back to its source.
Outcomes
What that looks like for you
Stop paying skilled people to retype paper.
Documents that used to be keyed in by hand now process themselves: extracted, verified, exceptions flagged. For one multi-site operator, that meant roughly 19 hours a week back at the first two locations alone, on track for payback in under six months.
~19 hrs/week recovered
We catch the bugs your vendors ship.
Silent data corruption costs quarters, not hours. When
invoice numbers started coercing into timestamps inside Microsoft’s
own kiota-python SDK, we diagnosed it, wrote the fix, and
Microsoft merged it. That’s the depth of debugging your systems get.
Read the PR
Merged upstream by Microsoft
AI that ships to production, with a paper trail.
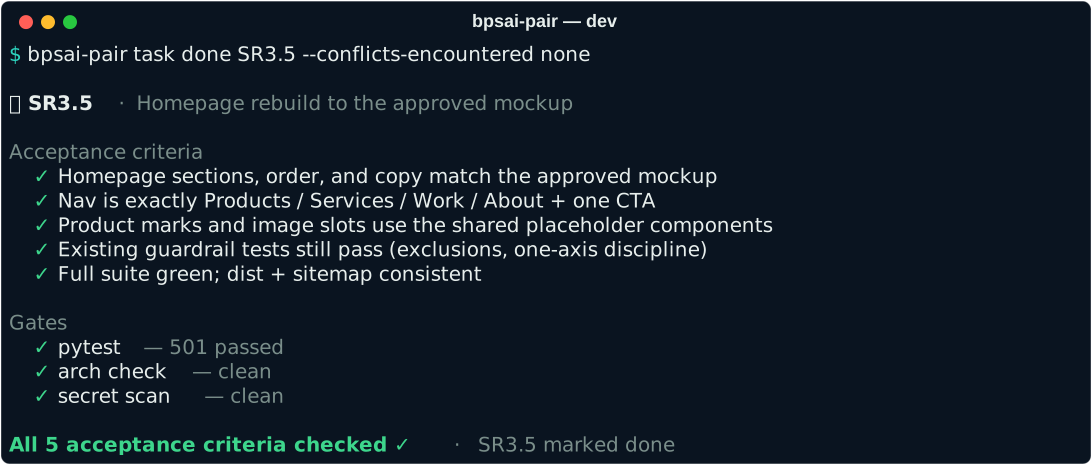
Every change PairCoder ships, ours and yours, passes enforcement gates backed by 19,448 tests, with benchmark-driven routing that picks the model that proves best on your actual task shapes. We run our own company on it every day. See PairCoder
19,448 tests · dogfooded daily
Products
Built here, run in production
Flagship
 PairCoder: Claude codes, Python
enforces
An AI development framework with enforcement gates that block the wrong behavior and benchmark-driven routing that learns which model wins your task shapes.

 Aurora
Pre-launch
Aurora captures meetings from a Chrome extension running locally in your tab, or from a file you upload. No bot ever joins a call, and you control capture. Every claim is cited back to its source moment, and action items sync to Trello, Slack, Google Tasks, and Jira.
Approach
Benchmark. Route. Cite.
The same discipline in everything we build: measure the field, send each job to the proven winner, and make every output traceable.
How we work01
Benchmark
Same fixtures, repeated runs, confidence intervals.
02
Route
Each task type to the model that measurably wins it.
03
Cite
Every answer traces back to something you can check.
In public
Receipts, in public
The Error Bars
Our benchmarking publication: repeated runs, confidence intervals, downloadable fixtures. Methods, data, and the uncertainty around them, in the open. A BPS team publication.
Pursue Index
An open, reproducible document-intelligence pipeline: a citable full-text index over public government document releases, with mandatory citations and published methodology, hash-pinned provenance, benchmarked OCR, and honest limitations.
Tell us the problem. If AI is the right tool, we’ll prove it.
You’ll talk to the people who’d actually build it, not a sales layer.
Start a conversation